Fireworks AI has released Ember-1, a post-trained version of Moonshot AI’s Kimi K3 that uses about 40% fewer tokens while trying to keep the same level of quality. Instead of simply telling the model to “think less” at runtime, Fireworks trained it to reason in a shorter and smarter way, which matters a lot for coding, tool use, and long agent tasks. Ember-1 is available as an API-only Research Preview through Fireworks Serverless, and while benchmark tests and customer A/B results look strong, the model weights, training code, and exact training methods have not been released.
Why Ember-1 Matters for Home Users and Developers
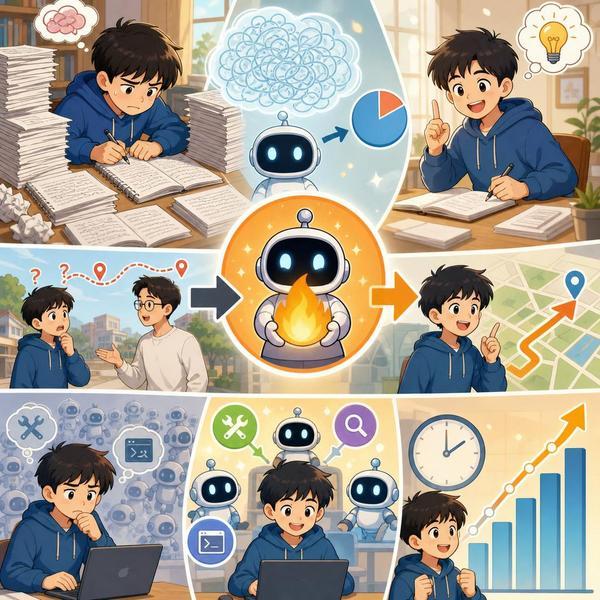
- Ember-1 matters because many reasoning models are like a student who writes three full notebook pages before giving a short answer to one math question.
- That long thinking process may look smart, but it also costs money because every extra token has to be generated, stored, and sometimes read again in the next step.
- Fireworks AI says Kimi K3 can spend more than 90% of its generated tokens on internal reasoning, which becomes a real problem in long multi-turn agent workflows.
- Think of it like asking a friend for directions, but before telling you “turn left,” they repeat the whole history of every road they have ever taken.
- In simple chat tasks, that may only feel annoying, but in coding agents, search agents, and tool-using systems, it becomes expensive very fast.
- If an AI agent takes 20 or 25 steps to finish one software task, it may keep dragging its old thoughts into every new step.
- That means early reasoning gets replayed again and again, which increases context size and cost.
- Fireworks built Ember-1 to fix this exact problem without badly hurting task performance.
- This is an important detail because lowering the reasoning setting is not the same thing as training a model to reason better.
- Lower settings often act like telling a runner to move slower and hope they still win the race.
- Post-training for efficiency is more like teaching the runner a better path so they use less energy and still reach the finish line at nearly the same speed.
- For developers building agents, this can mean fewer wasted tokens, smaller bills, and smoother production use.
- For teams watching every API dollar, a model that keeps quality while speaking less can feel like replacing a car that burns too much fuel with one that goes just as far on less gas.
- That is why Ember-1 is not just another model launch but a direct answer to the growing “token tax” in practical AI systems.
How Fireworks Used Research to Train Shorter Reasoning
- Fireworks says Ember-1 was created by post-training Moonshot AI’s open-weight Kimi K3, which means the base model already existed and then got extra training for a more specific goal.
- That goal was not to remove thinking completely, because not all reasoning is useless.
- Some reflection helps a model notice mistakes, react to tool feedback, and update its plan during a hard task.
- So the research challenge was to cut wasted loops while keeping useful self-checking.
- Imagine cleaning a backpack before school.
- You do not throw away your books, but you do remove broken pens, snack wrappers, and random papers you do not need.
- Ember-1 seems to follow that same idea by keeping helpful reasoning and dropping repeated or unproductive chains of thought.
- According to Fireworks, the training collection covered math, coding, instruction following, conversation, search, tool use, and software engineering.
- That matters because shorter reasoning in only one narrow area would not be enough for real-world use.
- A coding agent may need to read docs, call tools, check outputs, and then explain results to a user in plain language.
- Fireworks also said the work included both standalone tasks and longer multi-step interactions.
- That is important because long tasks are where token costs grow the fastest.
- The company ran more than 50 training experiments and over 200 evaluations, which suggests the final result came from repeated testing and adjustment rather than a single lucky run.
- Task and environment feedback were used for on-policy planning and learning, meaning the model learned while reacting to what happened during tasks.
- This is a bit like learning to ride a bike by making small balance fixes while moving, instead of only reading a manual about bicycles.
- Fireworks also said it created new training algorithms, but those details have not been published.
- All training ran on Fireworks Serverless Training, and the company says it used its own data rather than customer data.
- That privacy point may matter for enterprise users who worry about their internal code or business data being reused in training.
- Still, because the weights and code are not public, outside researchers cannot yet reproduce the method or inspect it deeply.
- So the training story is promising, but some parts remain closed behind the company’s research wall.
What the Benchmarks Say Across Tutorials, Coding, and Tool Tasks
- The benchmark results are one of the strongest reasons people are paying attention to Ember-1.
- Fireworks compared Ember-1 against Kimi K3 at low, high, and max reasoning effort levels.
- On Terminal Bench 2.1, Ember-1 scored 82.0%, which beat K3 Max at 80.9%.
- On DeepSWE 1.1, Ember-1 scored 75.2%, which was also better than K3 Max at 66.4%.
- These are meaningful wins because they show Ember-1 was not only cheaper in token use but also stronger on some difficult engineering-style tasks.
- At the same time, the model was not best on every benchmark.
- On SWE-bench Verified, Ember-1 scored 92.2%, slightly below K3 Max at 93.2%.
- On SWE-Interact, Ember-1 reached 20.0%, also slightly below K3 Max at 21.3%.
- This matters because it shows the results are more believable than a claim that says “we win everywhere.”
- Real AI systems often improve one thing while giving up a little somewhere else.
- What makes Ember-1 interesting is that the tradeoff appears small while the token savings are large.
- Fireworks says reasoning was shortened by 35% to 50% across seven benchmarks and two customers’ production traffic without sacrificing accuracy.
- That is a big statement because in AI, cheaper usually comes with weaker quality.
- If those numbers hold in wider use, Ember-1 could become a useful option for teams that need a model to solve complex tasks many times per day.
- Fireworks also highlighted Doximity’s Bedside Bench, a physician-validated set of 500 clinical cases, where Ember-1 reportedly reached a new cost-per-task Pareto frontier.
- In simple words, that means it gave a very strong balance between quality and cost.
- For SEO readers searching terms like “Ember-1 benchmark results,” “Kimi K3 vs Ember-1,” or “reasoning model token efficiency,” these numbers are the heart of the story.
- They suggest Ember-1 is not merely shorter in output but more disciplined in how it spends its reasoning budget.
- It is like seeing two students take the same test, but one writes a cleaner answer sheet, finishes sooner, and still gets almost the same or even a better score.
- That kind of efficiency is exactly what many AI product teams have been waiting for.
API Access, Pricing, and the Real Cost Story Behind Voice AI Era Workloads
- One of the most practical parts of this release is the pricing story.
- Ember-1 costs the same per token as Kimi K3 on Fireworks: $3.00 per 1M input tokens, $0.30 per 1M cached input tokens, and $15.00 per 1M output tokens.
- At first that may sound like there is no price benefit at all, but the savings come from using fewer tokens in the first place.
- That is a bit like two printers charging the same price per page, but one printer needs only 6 pages to explain something while the other needs 10 pages.
- In the published A/B example, output tokens dropped from 49.3K to 29.9K per task.
- Reasoning tokens fell by 71.3%, and total tokens fell by 39%.
- The task score was almost unchanged at 0.753 for Ember-1 versus 0.751 for K3.
- Average steps also decreased from 23.8 to 21.4.
- Using Fireworks pricing, the output-only cost works out to about $0.74 versus $0.45 per task.
- That may not sound huge for one task, but in production it adds up quickly.
- If a company runs 100,000 tasks, that difference becomes tens of thousands of dollars.
- This is why token efficiency is becoming a business issue, not just a model design issue.
- Fireworks says Ember-1 is already being used in production by at least one customer.
- However, deployment options are limited because Ember-1 is only available as an API-only Research Preview through Fireworks Serverless.
- It is also available through OpenRouter using the Fireworks endpoint at the same pricing.
- There is no self-hosting option right now because the model weights, training code, and exact learning methods have not been released.
- That means companies that need full control, offline use, or deep model inspection may hesitate.
- For those teams, the lack of open release is like being allowed to drive a fast car only on the maker’s track, not in your own garage.
- But for teams that already prefer managed APIs, Ember-1 may still be a very attractive option, especially for coding, support agents, and complex workflows where each saved token lowers the total bill.
Robotics Lessons from Ember-1 for the Future of Agentic AI
- Even though Ember-1 is not a robotics model, its biggest lesson fits robotics and agentic AI very well: smart systems need to act with focus, not just with more words.
- In robotics, a machine that pauses too long, rechecks everything too many times, or repeats old steps can waste power and time.
- The same thing happens with software agents that overthink before taking the next action.
- A useful agent should be like a good mechanic who checks the engine carefully, but does not take the whole car apart every time the oil light turns on.
- Ember-1 shows that AI progress is no longer only about getting higher scores.
- It is also about using compute more wisely, especially for long chains of actions.
- This matters for agentic AI, where the model may search the web, open tools, edit code, run tests, read logs, and answer the user all in one session.
- Each extra reasoning block becomes part of the next prompt, which makes future calls heavier.
- That snowball effect is why Fireworks focused on shorter reasoning traces instead of just fast answers.
- A shorter trace can make the whole session lighter from start to finish.
- Picture a hiker carrying supplies up a hill.
- If the backpack gets bigger at every stop, the trip becomes harder and slower.
- If the hiker keeps only what is useful, the full journey becomes easier.
- That is very close to what Ember-1 tries to do inside long AI tasks.
- For the future, this could push more labs to train models for efficient reasoning instead of only maximizing raw thinking length.
- It may also influence how AI infrastructure companies measure value, because users increasingly care about cost per finished task, not just benchmark glory.
- Still, people should remember that Fireworks published these results itself, so wider outside testing will be important.
- Until more independent evaluations appear, Ember-1 should be seen as a very promising research preview rather than a final answer for every workflow.
- Even so, the model points toward a simple but powerful idea: in AI, better thinking may sometimes mean thinking with less waste.
Conclusion
Ember-1 shows a clear new direction for reasoning models: keep the brains, cut the waste. Fireworks AI says the model delivers Kimi K3-like quality with about 40% fewer tokens by using post-training instead of just lowering reasoning effort at runtime. Benchmark scores, production A/B tests, and cost-per-task results suggest this approach may help developers run coding and agentic workloads more efficiently. The biggest limitation is access, because Ember-1 is still an API-only Research Preview with no released weights or training code. Even so, Ember-1 makes one thing very clear: in the next stage of AI, efficiency may matter just as much as raw intelligence.
