TinyFish makes search free, but that does not mean an AI agent reads the web for free. The real cost comes from two places: the search or fetch request itself, and the much bigger hidden cost of sending all that web content into an AI model as tokens. This matters because the article “TinyFish Makes Search Free: What It Really Costs an AI Agent to Read the Web” shows that one page can be tiny or huge depending on the provider, and that difference changes budget, speed, and context space in a big way.
Search Costs Are Only the Front Door
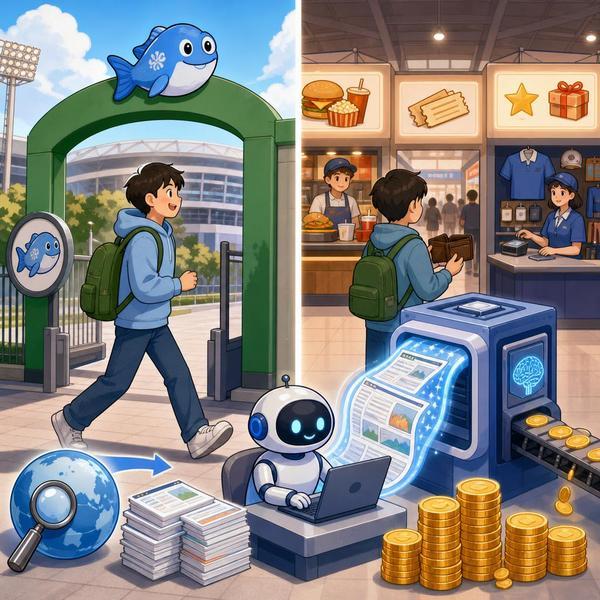
- When people hear that TinyFish offers free Search and Fetch within its limits, it sounds a bit like hearing that parking is free at a stadium.
- That sounds great at first, but once you walk inside, you still need to buy food, tickets, and maybe pay for extras, and in the same way, an AI agent still pays model processing costs after the page is found.
- The article makes a simple but important point: web-reading agents usually face two bills, not one.
- The first bill is the retrieval charge, which is what a search API or fetch API charges for finding or pulling a page.
- The second bill is the model bill, which starts when the returned content enters the model’s context window and becomes input tokens.
- After that, the model may also use more tokens while thinking through the task and writing an answer.
- This means “free search” does not equal “free agent work.”
- It only removes one layer of cost, while the larger layer may still remain.
- A good real-life example is asking a student helper to research a topic.
- If the library lets the student enter for free, that helps, but the time needed to read ten thick books is still real work.
- For AI agents, tokens are that reading work.
- The article explains that many teams carefully compare model prices but forget to ask how much text their search and extraction tools return.
- That is a costly mistake because a messy or oversized page can flood the model with extra tokens.
- Even if each token is cheap, thousands of extra tokens repeated many times can turn into a large bill.
- TinyFish says this hidden token load is often underestimated, and the article gives solid examples to show why.
- TinyFish also says its Search is free up to 30 requests per minute and 500 per hour, while Fetch is free up to 150 URLs per minute and 1,000 per day.
- Those limits make it attractive for builders who want to test agent workflows without paying a retrieval fee at the start.
- Still, anyone building serious AI agents should remember the main lesson here: finding the page is only the front door, and reading the page is where much of the money disappears.
Tokens Grow Fast When Fetch Gets Noisy
- One of the most eye-opening parts of the article is the comparison of how different providers returned very different amounts of text from one web page.
- This matters because more characters usually mean more tokens, and more tokens mean a higher model bill.
- For one Daily Mail article with about 4,300 characters in the main body, TinyFish Fetch returned 4,737 characters, which was estimated at about 1,184 tokens.
- Exa Contents returned 65,793 characters, around 16,448 tokens.
- Firecrawl Scrape returned 171,095 characters, around 42,774 tokens.
- Tavily Extract returned 46,433 characters, or about 11,608 tokens.
- Parallel Extract returned only 600 characters, about 150 tokens, but that was only an excerpt, not the full article.
- This is a huge spread, and it shows how the same web page can become a very different input depending on the extraction tool.
- You can think of it like ordering orange juice.
- One provider gives you a clean glass of juice.
- Another gives you juice, pulp, peel, seeds, the carton, and maybe the whole tree.
- The second one gives you more stuff, but not all of it is useful.
- That extra stuff still has to be processed, and AI models charge for processing.
- The article uses an example price of $1 per 1 million input tokens just to show the shape of the cost.
- At that sample rate, TinyFish’s output for that page would cost about $0.00118 in input processing, while Firecrawl’s output would cost about $0.04277.
- That may sound tiny for one page, but the difference becomes very real when an agent reads hundreds or thousands of pages every day.
- If a company runs many agent tasks, noisy extraction is like leaving a water tap dripping all month.
- Each drop seems harmless, but together they waste a lot.
- The article is careful and fair here, too.
- It says this was just one webpage example, so people should not assume the same ratio will happen on every site.
- That warning is important because benchmarks can guide decisions, but one sample should not become a rule for every use case.
- Even so, the lesson stands strong: the size of returned content changes token use more than many teams expect.
Context Windows Break Like Overpacked Backpacks
- Another key point in the article is that big pages do not only cost more money, they also take up valuable room inside the model’s context window.
- A context window is like the amount of text the model can hold in its short-term memory at one time.
- If that memory gets too full, the agent has less room for instructions, chat history, tool outputs, and the final answer.
- The article gives a clear example using about 42,774 tokens from a large page extraction.
- That single page would use about one-third of a 128K-token context window.
- Three pages that large would push the total to about 128,322 tokens, which is already more than the full window.
- At that point, there is barely any room left for the actual task.
- This is easy to picture if you imagine packing a school backpack.
- If you stuff it with three huge textbooks, there may be no space left for your notebook, lunch, or pencil case.
- An AI agent has the same problem when large pages arrive unfiltered.
- The article adds one more important detail: agent loops often resend context again and again.
- That means the model may reread earlier content in later turns.
- Some systems lower the price with cached-input pricing, which helps, but caching does not make the tokens disappear.
- The text still lives inside the context and still uses room.
- So even when rereading is cheaper, too much noisy text can still hurt reasoning quality and limit what the agent can do next.
- This is why filtering, truncation, and summarization matter so much in agent design.
- A smart agent should not shovel whole websites into the model unless the task truly needs that much detail.
- The article also mentions TinyFish’s internal fetch quality evaluation, where usable coverage was measured with rules like at least 1,000 characters and a judged signal ratio above 30%.
- In that internal test, TinyFish showed 93% coverage, Tavily 80%, Exa 73%, Firecrawl 62%, and Parallel 58%.
- That does not prove one provider wins in every case, because the test was run by TinyFish and used only 45 URLs, but it does highlight how coverage and signal quality can affect downstream agent work.
- For builders, the practical takeaway is simple: if you do not control what goes into the context window, the model ends up carrying too much junk.
Why TinyFish Says Free Retrieval Makes Sense for Agents
- The article explains that TinyFish does not treat search as a fancy extra feature.
- Instead, it sees search as a basic part of execution, like storage or DNS in normal software systems.
- That is a smart framing because most users do not care which pipe carried the water, they care whether water came out of the tap when needed.
- In the same way, a business using an AI agent to compare products, fill out forms, or book something mainly cares whether the task gets finished correctly.
- TinyFish gives three reasons for offering free retrieval within set limits.
- First, it says shared infrastructure helps the economics work.
- Before Search became a product, TinyFish had already built browser fleets, stealth systems, session hydration tools, and elastic scaling.
- That means search can ride on top of systems the company already uses.
- Second, TinyFish says it built specialized web-native models designed for search, fetch, and live site interaction.
- That matters because a model trained for web tasks may need less wasteful intermediate work than a general-purpose model.
- Third, TinyFish says it does not want to become a giant indexing company.
- Instead of trying to mirror the whole web like a classic search engine, it wants to learn how tasks get done on the web.
- That focus changes product design in a big way.
- The pricing details in the article make the offer more concrete.
- Search stays free at 30 requests per minute and 500 per hour.
- Fetch stays free at 150 URLs per minute and 1,000 per day.
- Both continue even when the wallet balance is zero.
- On top of that, new accounts get $8 in wallet funds.
- TinyFish charges separately for Agent and Browser usage, with Agent priced at $0.016 per step and Browser at $0.002 per minute.
- A simple example makes this easier to understand.
- If a startup is testing a shopping assistant that visits product pages, free retrieval lowers the barrier to trying the workflow, but once the assistant starts reasoning across many steps, the paid parts begin to matter.
- So TinyFish is not saying the whole system is free forever.
- It is saying the search layer should not be the thing that stops people from building or testing agent products.
Benchmark Results Need a Careful Reading, Not Just a Quick Look
- The benchmark part of the article is interesting because it shows how easy it is to read a leaderboard too fast and come away with the wrong idea.
- Artificial Analysis kept the answer model fixed as GPT-5.6 Luna medium and changed only the search provider.
- That means model cost differences came from the returned payloads, the number of searches, and how much reasoning the model had to do.
- On the September 28, 2026 snapshot, TinyFish had a Search Index score of 71 and a total displayed benchmark cost of $9.30 per 1,000 tasks, with $0 search cost and 59.0 seconds per task.
- The article says that was the lowest displayed total cost among the 12 configurations shown.
- But there is a trade-off.
- TinyFish also had the lowest displayed score in that view, while Perplexity Search medium had the highest displayed score at 80.
- So this is not a clean “TinyFish wins everything” story.
- It is more like buying shoes.
- One pair may be the cheapest, but not the fastest for a race or the strongest for hiking.
- The right choice depends on what you need most.
- The article also warns that benchmark cost per 1,000 tasks is not the same as API price per 1,000 requests.
- That is a very important difference because one benchmark task may trigger multiple searches.
- It also notes that Artificial Analysis uses its own shared extraction layer, so the benchmark does not directly measure TinyFish Fetch quality.
- That means readers should avoid mixing two different things: leaderboard task results and TinyFish’s internal fetch evaluation.
- Both are useful, but they answer different questions.
- The competitor table adds more texture by comparing TinyFish with Exa, Firecrawl, and Parallel.
- It shows TinyFish leading on free retrieval pricing and having the lowest combined benchmark cost among those entries, while Exa and others may show different strengths in score or speed.
- For someone building an agent product, this is a reminder that picking tools is not about finding one magic number.
- You need to balance score, speed, extraction quality, retrieval price, and token load together.
- If your agent reads lots of pages, token efficiency may matter more than a small benchmark score gain.
- If your product needs faster responses, then time per task may become the deciding factor.
- Reading the benchmark carefully is a bit like reading a nutrition label.
- If you only look at calories and ignore sugar, salt, and serving size, you miss the full story, and the same is true here with AI agent economics.
Conclusion
TinyFish makes search free within rate limits, but the bigger lesson is that AI agents still pay to process what they read. The article shows that retrieval cost is only one part of the picture, while token volume, context window pressure, repeated calls, and extraction quality often matter even more. TinyFish stands out for low displayed benchmark cost and free Search and Fetch limits, but it also comes with trade-offs in score and task time. For anyone building AI agents, the smart move is to track not just how pages are found, but how much text is returned, how useful that text is, and how much it really costs the model to carry it.
Source: https://www.marktechpost.com/2026/10/18/tinyfish-free-search-ai-agent-token-cost/
