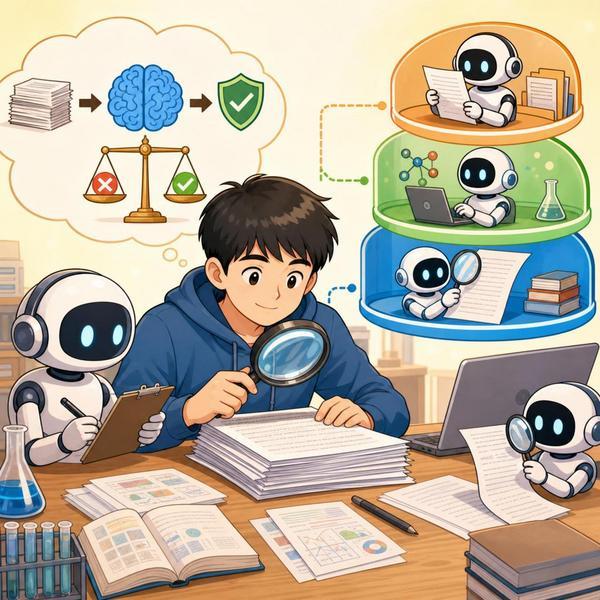
Sakana AI’s LLM peer review system catches 73% of core-claim errors, and that makes this research stand out in a big way. Instead of asking whether an AI reviewer sounds like a human reviewer, the team asked a much tougher question: can it spot a serious mistake inside a research paper? To test that, they built a large Contradiction Benchmark and a Multi-Layered Review system, and the results showed that system design, model choice, cost, and even reading method all matter when AI checks scientific work.
How the Agentic Review System Reads Like a Careful Student
- Sakana AI calls its method Multi-Layered Review, or MLR, and the idea is simple but powerful: before judging a paper, the AI should first try to understand it.
- That sounds obvious, but many older AI review tools worked more like a student who glances at the first page of a book and then gives an opinion right away.
- MLR slows down and reads in layers, which is a lot closer to how a careful teacher, researcher, or strong student would work in real life.
- The system uses three separate agents, and each one has a different job so the final review is not based on one fast guess.
- The Appendix Agent uses Claude Haiku 3.5 and focuses on experiments, settings, and implementation details that are often hidden in the back of a paper.
- This matters because many weak claims in research do not fail in the abstract or title; they fail in the small print where training data, baselines, and test settings are explained.
- The optional Literature Review Agent uses Claude Sonnet 4 with web search to compare the paper with older work, which helps the system ask whether the paper is truly new or just a dressed-up version of something that already exists.
- The main Review Agent also uses Claude Sonnet 4 and follows a three-pass reading style inspired by a well-known way of reading academic papers.
- In the first pass, it builds a high-level map of the paper, almost like drawing the outline before writing an essay.
- In the second pass, it reads more closely and looks for weak assumptions, missing evidence, confusing steps, or unsupported claims.
- In the third pass, it combines everything into a real review with strengths, weaknesses, questions, a recommendation, a score, and even a to-do list.
- A nice detail is that the system takes in the PDF directly, so figures, tables, and equations stay visible instead of being flattened into plain text.
- That is important because in science, one chart can change the meaning of a whole paragraph.
- Think of it like checking a recipe: if you only read the name and final photo, you may think it works, but if you read the ingredient list and cooking steps, you may notice the sugar and salt were swapped.
- For developers building AI Agents for science, this is the big lesson: better reviewing is not only about a smarter model, but also about a smarter reading process.
Why the Benchmark Uses Contradiction to Test Real Error Detection
- One of the smartest parts of this research is the benchmark, because Sakana AI did not just ask humans whether the AI review “felt good.”
- Instead, the team created a test where the answer could be measured much more clearly: did the reviewer catch a planted error or not?
- They collected 257 open papers from major research venues including ACL, AISTATS, CVPR, ICML 2025, and NeurIPS 2024.
- Then they built a structured map of each paper using Gemini 2.5 Pro, connecting claims, methods, and evidence like nodes in a graph.
- From there, the idea of distance becomes very important.
- If an error changes the main claim of the paper, it gets distance 0, which means it hits the heart of the work.
- If the error changes a smaller detail, it gets a larger distance, meaning it is still wrong but less central.
- GPT-4.1 then rewrote one node at each distance into a contradiction, which created 1,164 test cases across the paper set.
- This is a clever design because not all research mistakes are equal.
- Saying a model is faster by 2% when it is really slower by 1% is bad, but saying the whole method works when it actually fails is much worse.
- So the benchmark does more than count errors; it also measures how serious those errors are.
- To score the reviews, the team used an o3 judge model ten times for each review, which reduced the chance that one random judgment would distort the result.
- On clean papers, the judge reached 99.9% accuracy, which suggests it was very good at not inventing problems where none existed.
- It also showed 86.8% sensitivity on manually confirmed catches, so the reported numbers may even be a little conservative.
- You can think of this benchmark like a school science fair where some projects secretly contain wrong measurements, and the test is whether the judge notices the mistake instead of just praising the poster design.
- That makes this benchmark much more useful for SEO-driven discussions around AI peer review, scientific error detection, and benchmark design, because it focuses on real usefulness rather than surface-level similarity.
What the 73% Core-Claim Result Really Means in Practice
- The headline number is that MLR caught 73.43% of core-claim errors when four reviews were used, and that is the result most readers will remember.
- But the more interesting point is why this number matters so much.
- Core-claim errors are not tiny grammar problems or style issues; they are mistakes that hit the paper’s main promise.
- If a paper says, “Our method beats all past methods,” and that turns out to be false, that is a core-claim error.
- Finding these errors is much harder than sounding professional in a review.
- Among the tested systems, MLR was clearly ahead.
- The best baseline, AgentReview, found only 14.81% of distance-0 contradictions, while MLR found 73.43% with four reviews.
- Even a single MLR review caught 60.79%, which is still far stronger than the baseline systems listed in the study.
- The paper also ran an ablation study, which is a fancy way of asking, “What helped most: the model or the design?”
- When the researchers swapped GPT-4.1 out and used Claude Sonnet 4 inside LLM-Review, distance-0 detection jumped from 14.56% to 35.40%.
- That means model choice alone mattered a lot.
- But then MLR’s structure added about 25 more points on top of that in a single-review setup.
- So the results show a two-part truth: strong models matter, and strong workflow design matters too.
- It is like basketball: better shoes can help, but game strategy still changes the score.
- The system also did better on serious contradictions than on less central details, and that pattern actually supports the benchmark’s logic.
- If performance falls as the contradiction moves farther away from the main claim, that suggests the scoring system is capturing different levels of importance in a believable way.
- For anyone building tools for paper analysis, grant review, compliance review, or technical due diligence, this is a very practical result, because missing a core flaw can be far more costly than missing a small detail.
Where Human Scores, Retracted Papers, and Robotics-Like Limits Still Matter
- Even though the results are strong, the paper does not claim that AI peer review is solved, and that honesty makes the work more useful.
- First, the system only partly agrees with human reviewers.
- On ICLR 2025 submissions, MLR reached a Pearson correlation of 0.586 with human scores, while human-to-human agreement was 0.742.
- That means MLR often moves in the same direction as humans, but it still does not think exactly the same way they do.
- On ICML 2025, another system called AI Reviewer scored slightly better on this measure, at 0.439 versus 0.429.
- This shows that being best at finding contradictions does not automatically mean being best at matching human scoring behavior.
- The reason seems to be focus.
- MLR pays more attention to validity and experiments, while humans often place more weight on novelty and clarity.
- Imagine two movie judges: one cares most about whether the story makes sense, and the other cares most about whether it feels fresh and exciting.
- Both can be serious judges, but they will not always give the same number.
- The system also had a harder time on real retracted arXiv papers from WithdrarXiv-Check.
- There, MLR got 26.07% on similar matches and only 16.11% on exact matches.
- Those numbers are still better than many baselines, but they are far from the benchmark headline.
- This tells us that planted contradictions are useful for testing, but real-world bad papers can fail in messier ways.
- Some real papers may hide problems across many sections, weak comparisons, missing data, or misleading framing rather than one single contradiction.
- The paper also notes a security issue: hidden prompt injection still affects every AI reviewer tested.
- That is a big warning sign for researchers, publishers, and platform builders.
- In a way, this feels a bit like Robotics systems that can do amazing tasks in a lab but still trip over a toy on the floor in a real home.
- The core engine is impressive, but real environments are messy, tricky, and full of surprises.
Cost, Open Source Gaps, and the Tutorial Value for Builders
- Another reason this paper matters is that it gives numbers that developers can actually use when deciding whether to build or deploy a similar system.
- MLR costs about $0.47 per review, not counting the optional literature search agent.
- That is cheap enough to be practical for many labs, startups, or internal research teams, especially when compared with the cost of a human expert’s time.
- At the same time, it is not free, so repeated reviews across thousands of papers could still become expensive.
- The system uses about 189,062 input tokens per review, which is around half of what the AI Reviewer system consumed.
- That matters because token use often becomes the hidden bill in large-scale AI pipelines.
- The researchers also tested a single-prompt version that cut the cost by about two-thirds.
- The tradeoff was a drop of about 3.5 points in detection on a subset of the benchmark.
- So teams now have a realistic choice between cheaper reviewing and stronger reviewing.
- This is similar to choosing between a quick bike ride and a safer bus route in bad weather; the cheap option works, but not always as well.
- The comparison table also helps people see the full picture.
- LLM-Review was very cheap at about $0.01, but its contradiction detection was much weaker.
- AgentReview cost more than MLR and still did much worse on core-claim errors.
- AI Reviewer was close in price but consumed many more tokens and still trailed MLR on the contradiction benchmark.
- There is also an interesting point about openness.
- Some competing systems provide open code, while MLR’s code was listed as available on request in the report.
- For the Open Source community, that may affect how fast the method is tested, reproduced, and improved by others.
- From a builder’s view, this paper almost reads like a Tutorial for designing better research agents: read before judging, split tasks by role, keep access to figures and equations, compare cost against accuracy, and do not trust one metric alone.
- If someone wanted to build a paper-checking assistant for a university, a journal, or even a company research team, these lessons would be far more useful than a flashy demo with no benchmark behind it.
- There was no Python code in the provided source content, so there is no code block to reorganize here, and that is worth stating clearly to keep this post accurate.
Conclusion
Sakana AI’s Multi-Layered Review system shows that AI peer review gets much better when the model truly reads a paper instead of reacting fast. Its best result, catching 73.43% of core-claim errors, is far ahead of the baselines in the study and shows that workflow design matters as much as model strength. Still, the system is not a full replacement for human reviewers, because real retracted papers remain difficult, human scoring still differs, and hidden prompt injection is still a problem. The biggest takeaway is simple: in scientific review, AI becomes more useful when it is trained and structured to understand before it judges.
