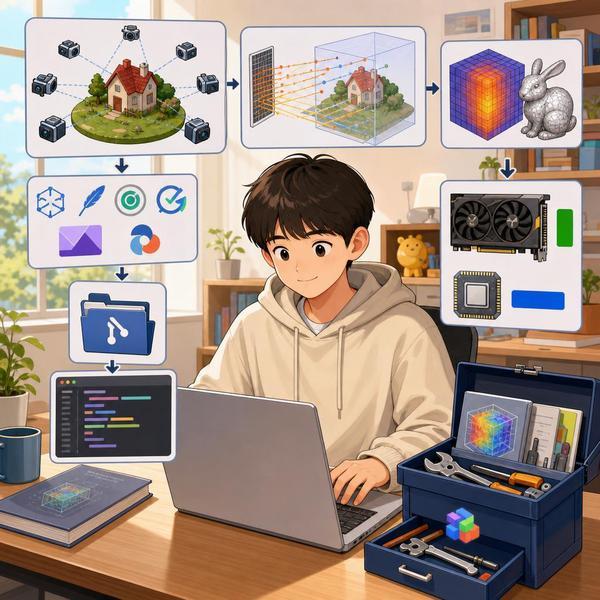
This tutorial shows how to build Hierarchical NeRF with JAX3D for volumetric rendering, novel-view synthesis, and 3D reconstruction in a full end-to-end way. It starts by making a synthetic 3D scene, placing cameras around it, and turning every camera view into rays, which is a lot like taking many photos of the same toy from different angles. Then it builds a NeRF model with coarse and fine networks, trains it with JAX, Flax, and Optax, and checks the result with PSNR, depth maps, opacity views, 360-degree rendering, and marching-cubes surface extraction. If you want to understand how a machine can learn a 3D world from 2D images, this is a very clear and practical example.
Home View: Setting Up the JAX3D World and Camera Pipeline
- The tutorial begins by preparing the full JAX3D environment, and this first step matters more than many beginners think.
- Before any 3D scene can be learned, the code installs support tools like Flax, Optax, chex, etils, and scikit-image so the model can train, render, and later extract geometry.
- It also clones the JAX3D repository and loads the volume rendering file directly, which is a smart choice because it avoids pulling in extra package parts that are not needed for this focused workflow.
- You can think of this like opening only the toolbox drawer you need instead of dragging the whole workshop into your room.
- The code checks whether the machine is using a GPU or only a CPU, and then changes the settings to fit the hardware.
- That simple hardware check is very practical because a full NeRF setup can feel fast on a GPU but very slow on a CPU.
- For a student trying this at home on a laptop, this is the difference between finishing a short demo and waiting all day for one training run.
- The configuration block controls image size, number of training views, near and far ray limits, number of samples, model width, batch size, training steps, and extraction grid size.
- These settings are like the knobs on a game graphics menu, where changing resolution and detail level affects both speed and quality.
- Next comes the camera setup, which is one of the most important parts of the whole tutorial.
- The look_at function builds camera-to-world poses so each camera points toward the scene center in a clean and consistent way.
- The orbit_poses function spreads many cameras around the object using golden-angle azimuth values and smooth elevation changes, which helps the model see the scene from many sides.
- That spread is important because a NeRF learns from what the cameras see, so weak camera coverage often leads to weak 3D understanding.
- The rays_from_pose function then turns each camera view into a grid of ray origins and ray directions.
- This is the moment where an image stops being just pixels and becomes a set of lines traveling through 3D space.
- If you imagine shining thousands of tiny flashlights from the camera into the scene, each flashlight beam is one ray.
- The code normalizes these rays, which keeps depth values meaningful and stable.
- In simple words, the model now has a clean geometric map for asking the same question over and over: what color and density live at this place in 3D space?
- That question is the heart of volumetric rendering, and the camera pipeline is what makes the whole learning problem possible.
Tutorials Walkthrough: Building a Synthetic Scene the Model Can Learn From
- After the environment is ready, the tutorial creates a synthetic training world instead of using a messy real image dataset.
- This is a strong teaching choice because it lets readers understand every part of the scene and know exactly what the model is trying to recover.
- The scene contains several soft-edged spheres, a floor plane with a checker pattern, and view-dependent shiny highlights.
- That means the scene has both shape and appearance changes, which is perfect for showing why NeRF models need to understand more than simple color lookup.
- Each sphere is defined by a center point, a radius, and a base color.
- The sphere field function computes density and RGB values from position and viewing direction, which means the color can change when the camera moves.
- This is similar to how a polished ball in your room reflects light differently when you walk around it.
- The density value tells the renderer how much matter is present at a point, while the RGB value tells it what color that matter should contribute.
- The floor field adds another useful learning target because it mixes geometry with a simple repeating texture.
- The checkerboard pattern is easy for humans to recognize, so it becomes easy to notice whether the model has learned it correctly.
- The full ground-truth field blends the spheres and the floor together using density-weighted colors.
- This is important because in volumetric rendering, different parts of space can overlap in influence along the same ray.
- The render_ground_truth function then uses JAX3D sampling and volume rendering to create RGB images, depth maps, and alpha values.
- In other words, the tutorial first shows the forward process, meaning how a 3D scene creates 2D images.
- That matters because the NeRF training process later tries to solve the reverse problem: learning the hidden 3D scene from those 2D results.
- The build_dataset function loops over all training and test camera poses, renders images for each one, and stores ray origins, directions, and colors.
- This creates a multi-view dataset from scratch, and every image is perfectly aligned with known camera geometry.
- For learning, the images are then flattened into a huge ray pool.
- That means the model does not need to eat full images at every step and can instead train on random ray samples.
- This is like studying a giant mural by looking at many tiny pencil lines one at a time until the full picture becomes clear.
- Because the data is synthetic, the tutorial avoids common real-world issues like camera calibration mistakes, blur, lighting shifts, or missing labels.
- As a result, readers can focus on the real lesson: how Hierarchical NeRF works from the inside.
Open Source/Weights Logic: How the NeRF Model Learns Shape and Color
- The NeRF model in this tutorial is built with a Flax MLP, and its design follows the classic idea that a network can learn a full 3D scene as a continuous function.
- Instead of storing a scene as a fixed voxel grid, the model takes a 3D position and a view direction as input and predicts density and color.
- This is powerful because it means any point in space can be queried, even points that were never directly seen during training.
- If a normal image is like a printed map, a NeRF is more like a smart map app that can answer questions anywhere you tap.
- The first key step is positional encoding.
- The posenc function takes simple coordinates and expands them using sine and cosine waves at many scales.
- This may sound strange at first, but it helps the network learn fine detail much better than raw coordinates alone.
- You can think of it like giving the model both a street address and multiple zoom levels of the same neighborhood.
- The NeRFMLP then uses these encoded positions as input to several dense layers.
- A skip connection is added partway through the network so the original encoded position can re-enter the computation.
- This helps preserve useful spatial detail and keeps training more stable.
- Without this kind of shortcut, deeper layers can sometimes blur away important information.
- The network predicts sigma, which is the density, using a softplus output so the value stays non-negative.
- That matters because density should not be negative in a physical rendering system.
- After that, the model adds encoded viewing direction information and predicts RGB values.
- This separates geometry from appearance in a clever way.
- The shape of an object should stay the same when you move around it, but shiny color effects can change with the angle.
- Imagine a red apple on a table: the apple stays round, but the bright white spot from the lamp moves when you change where you stand.
- The tutorial uses two copies of this network, one coarse and one fine.
- The coarse network gives a rough guess about where useful scene content lies along a ray.
- The fine network spends more effort near the most important regions and gives the final better-looking result.
- This two-stage design is the reason the method is called hierarchical, and it is one of the smartest ideas in NeRF because it saves compute while improving detail.
Applications of Hierarchical Sampling: Why Coarse and Fine Rays Matter
- The rendering core is where the tutorial becomes especially interesting, because this is where the model actually turns learned scene values into an image.
- For each ray, the code first samples a set of coarse depth values between near and far bounds.
- These sample points are converted into 3D positions, and the coarse network predicts density and color at each one.
- Then JAX3D volume rendering combines those predictions into a single pixel color, a ray depth, and an alpha value.
- This compositing step is similar to stacking many thin pieces of colored glass and asking what color reaches your eye after light passes through them.
- But the really clever part comes next.
- The renderer looks at the sample weights from the coarse pass and uses them as a probability guide.
- High weights mean that part of the ray likely passes through an important surface or region.
- The code turns those weights into a piecewise-constant PDF and uses sample_piecewise_constant_pdf to draw extra fine samples.
- This is much better than blindly placing more samples everywhere.
- It is like searching for lost keys by checking the places where you most likely dropped them instead of covering every centimeter of the room equally.
- The fine samples are merged with the original coarse samples and sorted by depth.
- Then the fine network predicts density and color again, this time with better coverage near surfaces.
- The final rendering from the fine network is the main output used for high-quality prediction.
- The code also stops gradients through the fine sampling positions.
- That may sound technical, but the idea is simple: the model learns from the rendering results without trying to backpropagate through the random sample-picking step itself.
- This keeps the optimization cleaner and more stable.
- Hierarchical sampling is a big reason NeRF became so effective.
- Most of empty space along a ray contributes very little to the final image, so using equal effort everywhere wastes time.
- This tutorial makes that idea very clear by storing the coarse depths, coarse weights, and fine samples for later visualization.
- When you later see those plots, the method feels much less like magic and much more like a smart search strategy.
- That is one reason this example is useful for learners who want to move from copying code to truly understanding the rendering logic.
Newsletter Results: Training, Evaluation, Orbit Rendering, and 3D Extraction
- Once the model and renderer are ready, the tutorial trains the coarse and fine networks together.
- It initializes model parameters with random keys, counts the number of parameters, and sets up an Optax optimizer with Adam, learning-rate decay, and gradient clipping.
- These choices are practical and popular because NeRF training can be sensitive if updates become too large or too noisy.
- The train_step function computes both coarse and fine RGB losses against the target ray colors and updates the model with JAX JIT for speed.
- That means the coarse network is not ignored after sampling, and both stages are pushed to improve.
- During training, the code samples random rays from the full ray pool, which is an efficient way to learn from a large dataset without rendering all images every step.
- This is like practicing basketball by taking many focused shots instead of replaying the full game every minute.
- The tutorial tracks PSNR, which gives a simple measure of how close the predicted images are to the ground truth.
- After training, the model is tested on held-out camera views that it did not see during optimization.
- This is the true test of novel-view synthesis, because the goal is not to memorize images but to generate new views correctly.
- The code renders full test images in chunks so memory use stays manageable.
- It then shows ground truth, predicted RGB, depth maps, and opacity maps side by side.
- These extra views are important because a nice color image alone can hide failures in geometry or transparency.
- The tutorial also visualizes one ray’s coarse weights and fine samples.
- This gives a very intuitive picture of how the model first searches broadly and then zooms in near the surface.
- It feels a bit like drawing a rough pencil sketch before adding the sharp ink lines.
- Next comes a 360-degree orbit GIF, which is one of the most satisfying outputs in the whole pipeline.
- Seeing the learned scene rotate makes it clear that the model is storing a real 3D representation rather than just patching together flat images.
- Finally, the code queries density on a 3D grid and runs marching cubes to extract an isosurface.
- This step turns the learned field into an approximate mesh, which gives a bridge from neural rendering to classic 3D geometry.
- In simple words, the model goes from learning “where stuff is in space” to giving you a surface you can actually visualize as shape.
- That full journey from synthetic scene generation to reconstruction quality, orbit rendering, and mesh extraction is what makes this tutorial feel complete rather than partial.
Conclusion
This Hierarchical NeRF with JAX3D tutorial gives a full and practical view of volumetric rendering, novel-view synthesis, and 3D reconstruction. It explains how to build synthetic multi-view data, create rays from camera poses, train coarse and fine NeRF networks, and use importance sampling to focus compute where it matters most. It also shows why evaluation tools like PSNR, depth, opacity, orbit rendering, and marching cubes are useful for checking both image quality and learned geometry. For anyone learning neural rendering, this is a strong example because it connects the math, the code, and the visual results in one clear pipeline.
